Mike Taylor is the head of evals at Every and a co-author of "Prompt Engineering for Generative AI" (O’Reilly).

Context Engineering Is Knowing When to Start Over
Old instructions and earlier mistakes can derail your AI chats. Here’s how to reset without losing useful work.
Oct 16, 2026 · 11 min read

Was this newsletter forwarded to you? Sign up to get it in your inbox.
The people I work with know I keep Claude’s memory turned off. The same goes for ChatGPT. I’ve written before about why: Memory can be useful, but it can also bring old preferences and irrelevant instructions into a conversation where they don’t belong.
Turning memory off doesn’t entirely solve the problem. Even within a single thread, context can accumulate in ways that make the model’s responses worse—a problem known as context rot. It might keep following instructions you’ve moved on from, build on an earlier mistake, or overlook a crucial detail buried in the conversation.
That’s why I start a fresh thread for every task. If the task changes, I open a new chat—even if it’s for the same project I was working on five minutes ago.
In my forthcoming book, Context Engineering with DSPy, I explore the seven ways in which context goes wrong and what to do about it. The book is written for engineers building AI products, but I’ve adapted the examples that follow—inspired by Drew Breunig’s “How Long Contexts Fail”—for anyone who uses AI chat. They’ll help you recognize when a conversation has gone off track and restart without losing useful work.
1. Context distraction: Old patterns constrain new answers
AI models are trained to follow the instructions in their prompt very closely, which is usually what you want—up to a point. There’s a trade-off between compliance and creativity: The more context you provide, the more the responses are constrained to what’s already in the conversation. You want AI to follow your instructions but also use good judgment when following the rules would give you a worse result.
One example I use to demonstrate this problem in AI training workshops is asking ChatGPT to name a new product the way Steve Jobs would. With instructions alone, 21 percent of the names it comes up with start with “i-” (iPod, iPad, iPhone). Once I add a handful of example names that start with “i-” to the prompt, 100 percent of the names ChatGPT gives me start this way. That’s great if rigid compliance is what you want, but the model also stops suggesting any of the names I liked that didn’t fit the pattern.
In a long thread, everything you worked on earlier becomes an example the model follows moving forward, whether you mean it to or not. It treats everything you’ve said as gospel, which will constrain its creativity in subtle ways you might not notice—unless you start a new thread without that old context. Models struggle to make the judgment call that the conversation has moved on, and old instructions no longer apply. You have to make that call for them.
Watch for: You ask for a different direction, but every suggestion still follows the pattern of the examples you gave earlier.
What to do: Start a new thread whenever the tone or type of task changes. When you do want the AI to follow examples, add them on purpose and test how many you actually need to let the model be creative, within the constraints you’ve set.
2. Context confusion: Irrelevant details steer the response
AI models don’t do a good job of ignoring information that has nothing to do with the task. If it’s in the prompt, even if it isn’t relevant to what you asked, the model assumes it must be there for a reason, and it tries to use it in its response.
My colleague Katie Parrott found this out the hard way when the instructions for her writing style guide grew from 759 words to 3,855, and the writing became so bad it was unrecognizable. The model treated every line as a requirement and tried to satisfy all of them at once, so the drafts got worse with each round of feedback—one essay took 127 drafts and more than 1 million words. The solution was to take instructions away: The rebuilt style guide runs 513 words.
To prepare for an interview at Microsoft Build, I interviewed an AI version of GitHub’s COO, Kyle Daigle, built with a modified version of the open-source library SynthTeam using his public writing, talks, and interviews. It answered five of my 12 questions with the must/should/could prioritization framework. Daigle had written about this framework on his website, so the virtual version overindexed on it despite the fact that it wasn’t relevant to the questions I was asking. When I spoke to the real Daigle, he never mentioned the framework once.
Watch for: The model keeps bringing up a fact, preference, or framework that has little to do with your current question.
What to do: Keep memory turned off so irrelevant context can’t leak into the current conversation. Keep your custom instructions to a minimum, because they can affect every conversation you have in ways you couldn’t have anticipated. One offhand comment can affect responses across your chats, and it may be hard to trace the problem back to its source.
3. Context neglect: Details in the middle get overlooked
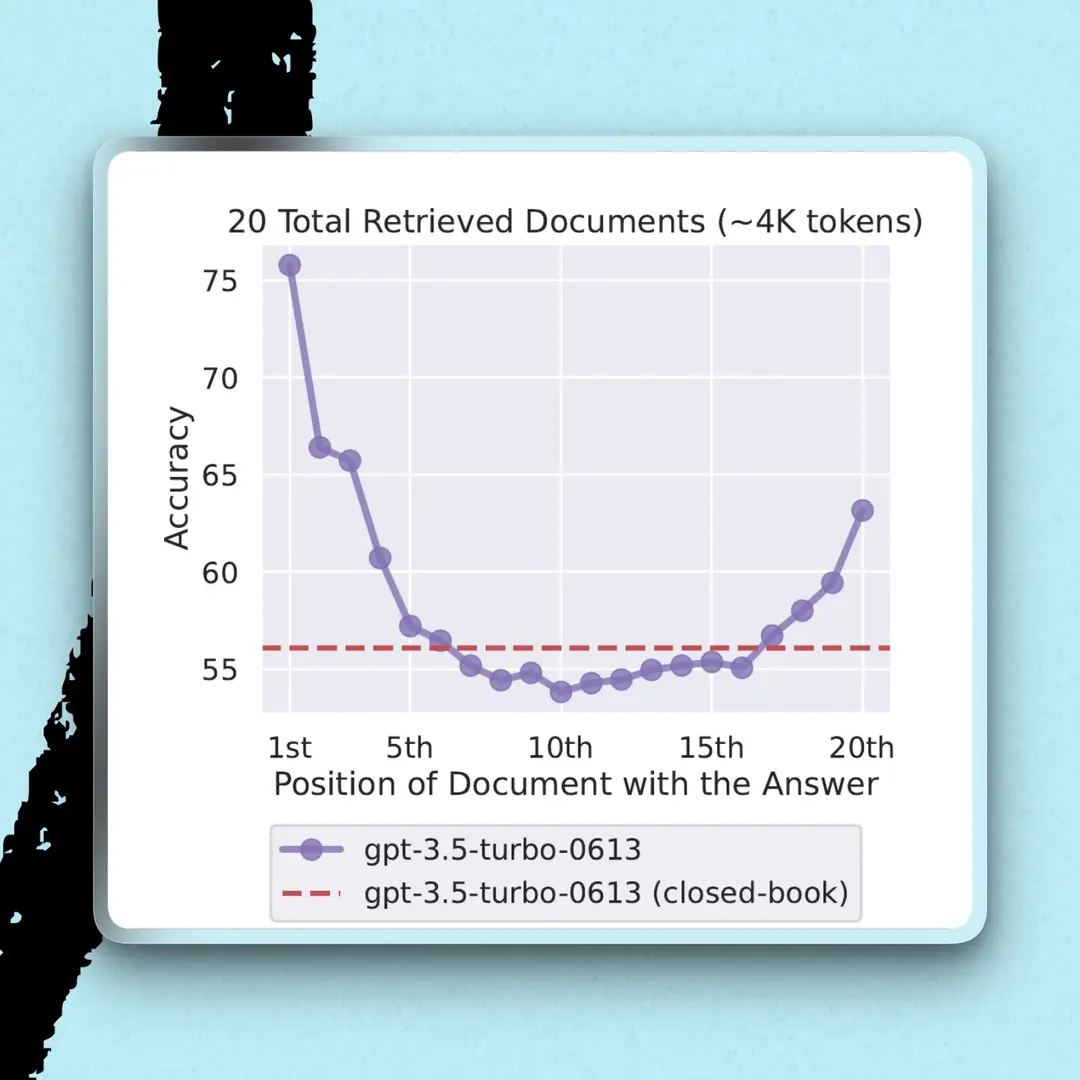
Researchers from Stanford found that AI models pay the most attention to the beginning and end of their context, and performance drops significantly when the information they need is in the middle. Humans show a similar pattern: We tend to remember and give more weight to information we encounter first or last, known as primacy and recency bias, respectively.
In the book, I run an experiment where I give a model nine documents about a project, with a critical bug report sitting at position six, and ask about the main risks to the project. The model answers based on the overview at the start and the launch plan at the end and ignores the bug report completely. The same thing happens when you upload a stack of PDFs or paste in a long meeting transcript and ask the model a question about it: The answer leans on whatever came first and last, and the longer the thread, the bigger that middle gets.
Watch for: The answer skips a crucial detail in the middle of your documents, even while accurately referencing others.
What to do: Only upload the documents the task needs, and if you have several questions about different documents, ask them in separate threads. Prompt engineers have long put the important task information at the top of the prompt and the formatting instructions at the bottom, and it’s worth doing the same with your messages.
4. Context drift: The original goal slips out of focus
As new information piles up, the model can lose track of your original goal. Its answers stay coherent, but it stops following your initial set of instructions. Maybe you’ve experienced this after a long conversation with Claude or ChatGPT—it starts to introduce new angles, focus on the wrong things, or say “let’s step back” or “let’s wrap this up” when your initial goal is not yet accomplished.
In the book, I show the example of a coding assistant told to “follow PEP-8 strictly” (a Python style guide) at the start of a conversation, and 50 messages later it’s writing code that completely ignores the guide. You’ve probably seen the everyday version: You tell the AI at the start of a thread to use British spelling or to keep its answers fewer than 200 words, and an hour later it has slipped back into its defaults.
Watch for: The AI starts ignoring something you told it earlier, such as a spelling guideline or word limit.
What to do: Keep the preferences you always want—like spelling, tone, or length—in a saved document and paste them in at the top of every new chat. To save on token costs, Claude and Codex both condense the chat into a summary when it grows too long (more tokens cost more to process), but that can come at the cost of losing prior details and important instructions.
5. Context clash: Early assumptions conflict with new information
Researchers from Microsoft and Salesforce took prompts that would normally be given in one go and split them into several step-by-step messages, the way most of us actually talk to AI. However, breaking the task up led to 39 percent worse results across models. AI models tend to make assumptions early and jump to an answer before they have all the information, and that early answer stays in the thread, clashing with whatever you tell the model next.
When I was automating PowerPoint decks for a client, the initial results were terrible. The solution was to give the AI the whole picture before it started building anything. We had it write a blueprint and a detailed agenda from our call notes first, and it rarely missed a slide.
Watch for: You clarify the brief, but the model keeps building on an assumption it made before you supplied that information.
What to do: Write the full brief before you start and put everything the model needs into the first message rather than drip-feeding it. If you realize halfway through that you left out something important, start a new thread with the complete brief, so the model never gets the chance to commit to the wrong answer.
6. Context poisoning: Earlier errors contaminate later answers
The term “context poisoning” comes from Google’s Gemini 2.5 technical report. The Gemini team had an AI agent play Pokémon Red. In one case, it confused the game with a later remake and decided it needed an item called TEA to get past a guard. But that item doesn’t exist in the version it was playing. Gemini wrote down that goal and spent more than 100 turns searching for something it could never find.
In a chat, a made-up statistic or a misremembered fact early on will show up again in every later draft because the model treats its own earlier answers as settled. Telling the model that it got something wrong doesn’t remove the mistake, either: The original error and your complaint about it are both still in the thread.
Watch for: A fact you’ve already corrected reappears in the next draft or becomes the basis for another answer.
What to do: When the AI makes a mistake, don’t argue with it in the thread or ask it to correct itself. Instead, go back and edit your previous message so it has no memory of doing anything wrong. With any mention of the mistake removed, it’s less likely to get stuck in a loop of making the same mistake. AI works by role-playing the helpful assistant it thinks you want. If it can see mistakes in its chat history, the model thinks it’s playing the role of “an AI that makes mistakes.” The past becomes a self-fulfilling prophecy. Both ChatGPT and Claude let you edit a message you already sent or regenerate the response, and either one is better than arguing with it.
7. Context underspecification: Missing details force the model to guess
Every cause so far is a problem of too much context, but context rot can also come from a model that has too little. If something important is missing from the prompt, the model has to guess, and its guess will be the average of its training data. ChatGPT’s output is the average of the internet, so the default answer is often bland and undifferentiated.
I used to run a 50-person marketing agency, so I know that value-based pricing often doesn’t work for agencies. But when you ask AI about pricing, it consistently recommends value-based pricing, echoing business pundits whose success with the strategy in niche businesses gets disproportionate attention online. Without the context that comes from running an agency, AI can mistake their advice for a broadly applicable rule. When you start a new thread with Claude or ChatGPT, you need to give it the context it needs. In this case, I used voice mode to explain what I’d learned from running an agency. Those details helped the model write a more useful post that reflected my experience. If you’re leaving a long thread that has valuable context but is starting to degrade from context rot, ask the model to save a handoff file—a document summarizing the key facts, decisions, and next steps. Upload it to a fresh thread so the model has what it needs to keep going.
Watch for: The answer could apply to almost anyone, leaving out the constraints or experience that make your situation different.
What to do: Before you leave a long thread, ask the model the question I’ve recommended when working on recurring tasks:
What information would have been useful to know at the start of this task that would have eliminated several steps or mistakes?
Read the answer, cut anything wrong or out of date, and paste it into your new thread as part of the new brief.
Making a habit of starting fresh
The best long-term fix for context rot is to keep your best context in local files your agent can read as needed. When I ran my agency, if I got the same question from staff or clients three or more times, I’d write a standard operating procedure and put it in a shared Google Drive folder. I do a similar thing with my prompts today: If AI needs an answer in one session, it might be useful in the next. I save prompts in Markdown files in GitHub, to reference when I start fresh, instead of hoping the right details survive in a long thread. By controlling which folder the agent is in, I can control its context and avoid context rot.
A model won’t get annoyed if you start over 15 times, and it won’t tell you when your thread has become a mess. Its output just gets worse, so it’s up to you to prevent context rot before it takes over. Starting a new thread every time means I know exactly what the AI is working with: only what I’ve given it.
Mike Taylor is the head of evals at Every, the author of O’Reilly’s Context Engineering with DSPy, and the coauthor of Prompt Engineering for Generative AI. You can follow him on X at @hammer_mt and on LinkedIn.
See how good you are at using AI—and learn how to get better
Sign in to read for free and get your AI assessment prompt.
Continue with GoogleView all login options Continue with Google
 Sign in


